NVIDIA has introduced a 64GB version of DGX Spark, extending its compact Grace Blackwell AI computer into a lower-memory configuration designed for developers running models and AI agents locally.
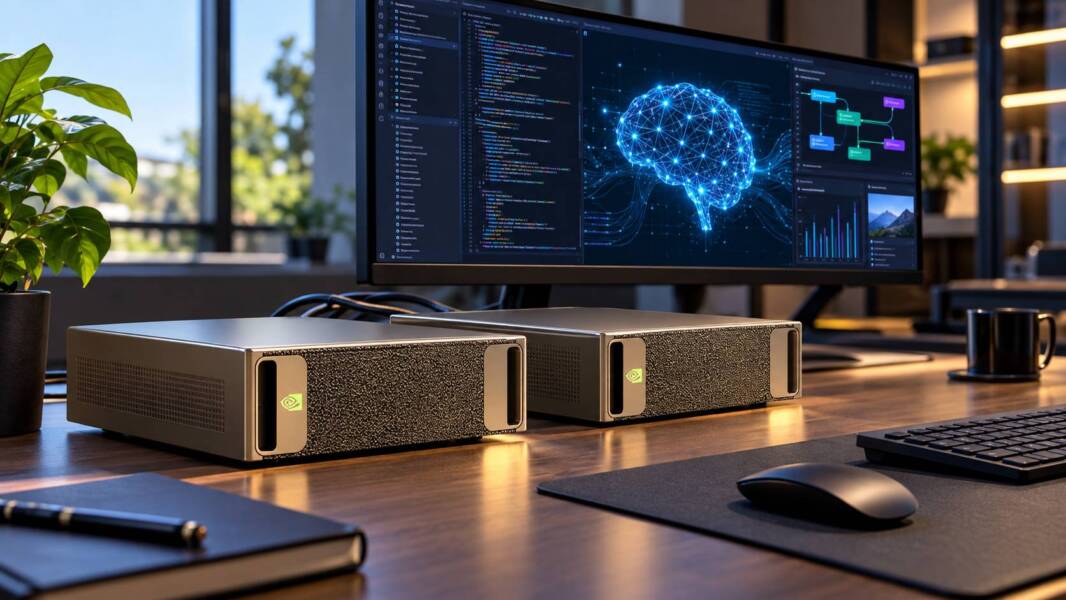
The new machine will be available beginning October 23, 2026, from Acer, ASUS, Dell, Gigabyte, HP and MSI, with configurations starting at $4,999. It retains the GB10 Grace Blackwell Superchip, DGX OS, ConnectX-7 networking and NVIDIA’s AI software stack used by the 128GB DGX Spark, but cuts unified memory to 64GB. NVIDIA Blog
That makes the announcement more significant than a straightforward product refresh.
NVIDIA is effectively defining a new tier of local AI infrastructure: powerful enough to run many current open models and persistent agents without sending workloads to a cloud service, while retaining a path to scale beyond one machine.
The trade-off is memory.
NVIDIA says a single 64GB Spark supports models with up to 100 billion parameters. Connecting two systems through their built-in ConnectX-7 interfaces can pool memory to 128GB, expand model support to as much as 200 billion parameters and, in NVIDIA’s own Qwen 3.8 27B testing, deliver as much as 1.7 times the performance of one system. NVIDIA Blog
For developers considering local AI infrastructure, that distinction matters: the 64GB DGX Spark is not simply a cheaper 128GB Spark. It is a bet that increasingly efficient models, quantization and small-scale clustering will make 64GB a practical starting point for serious local AI development.
What NVIDIA changed in DGX Spark
The fundamental architecture remains intact.
DGX Spark combines NVIDIA’s GB10 Grace Blackwell Superchip with unified CPU-GPU memory, ConnectX-7 networking and a CUDA-accelerated software environment intended specifically for AI development.
The new configuration includes 64GB of unified memory instead of 128GB.
NVIDIA says it otherwise retains the same core platform and software environment as the larger system. Supported software includes CUDA-X libraries, the NVIDIA Agent Toolkit and Nemotron models, alongside widely used frameworks and runtimes such as PyTorch, Ollama and vLLM. NVIDIA Blog
The company positions the system for inference, AI-agent development, fine-tuning, data science and edge-development workloads.
The most important specifications are therefore:
| Feature | DGX Spark 64GB |
|---|---|
| Processor | NVIDIA GB10 Grace Blackwell Superchip |
| Unified memory | 64GB |
| Local model support | Up to 100B parameters, according to NVIDIA |
| Networking | ConnectX-7 |
| Multi-node connection | Direct connection via QSFP |
| Two-system memory | 128GB pooled |
| Two-system model support | Up to 200B parameters |
| Software | DGX OS and NVIDIA AI software stack |
| Starting price | $4,999 |
| Availability | October 23, 2026 |
The 64GB configuration will be sold through manufacturing partners rather than as an NVIDIA Founders Edition. NVIDIA Blog
Why 64GB can now be useful for local AI
At first glance, halving the memory of an AI workstation sounds like a substantial compromise.
It is.
But the software environment surrounding local AI has also changed.
Model developers have increasingly produced smaller architectures, mixture-of-experts designs and aggressively quantized versions capable of delivering useful performance without loading hundreds of gigabytes of weights.
That has shifted the practical question from How large is the model? to How much memory does this particular model configuration actually require?
NVIDIA explicitly argues that increasingly capable open models now fit comfortably within smaller memory footprints, leaving capacity available for the operating system, context, KV cache, tools and other components needed by AI agents. NVIDIA Blog
That is particularly important for agentic workloads.
A local coding agent, for example, might need more than the language model itself. It can also require a substantial context window, embeddings, retrieval components, development tools and potentially several concurrent processes.
NVIDIA lists persistent coding and research agents, local AI applications and larger clustered workloads among the practical use cases for DGX Spark. NVIDIA Blog
In other words, 64GB should not automatically be interpreted as 64GB available for model weights.
The operating system and runtime consume memory, as does inference state. Long context windows can substantially increase memory requirements through the KV cache.
For prospective buyers, that makes the headline “up to 100 billion parameters” a ceiling rather than a guarantee that every 100B model or configuration will be comfortable to operate.
Parameter count alone is an increasingly poor proxy for actual memory requirements.
Precision, quantization format, model architecture, context length, batch size and runtime overhead all matter.
NVIDIA is making clustering part of the desktop AI proposition
The more interesting component of the announcement may be NVIDIA Sync.
Every DGX Spark contains a ConnectX-7 network interface. Two systems can be directly connected using a QSFP cable.
NVIDIA says its new Sync Cluster Assistant detects the connected machines, checks their configuration and sets up the ConnectX-7 network automatically. Because both machines use the same NVIDIA software environment, developers do not need to rebuild the stack when moving a workload from one node to two. NVIDIA Blog
Two 64GB systems provide 128GB of pooled memory and twice the aggregate memory bandwidth, according to NVIDIA.
The company says the resulting cluster supports models up to 200 billion parameters.
More significantly, NVIDIA reports that two 64GB DGX Spark systems achieved up to 1.7× the performance of one Spark when running Qwen 3.8 27B. NVIDIA Blog
That number should be treated as a vendor benchmark rather than a universal scaling factor.
Distributed inference efficiency depends heavily on the model, framework, communication overhead and workload. Doubling the hardware rarely guarantees a linear doubling of application performance.
Still, making multi-node configuration approachable could remove one of the largest obstacles to experimenting with distributed AI outside a data center.
Model Launcher should simplify the next step
NVIDIA plans another component for later in October: NVIDIA Sync Model Launcher.
The company says the tool will allow developers to download and launch Qwen 3.8 27B on either a single DGX Spark or a cluster, while automatically configuring the model across the connected hardware.
It will also configure OpenCode to use the locally hosted model, allowing developers to interact with it through a browser. NVIDIA Blog
This is strategically important.
The value of local AI hardware increasingly depends not only on TOPS, FLOPS or memory capacity but on how much infrastructure work is required before a developer can actually use it.
Cloud AI became popular partly because developers could call an API rather than manage accelerators, drivers, model servers and distributed infrastructure.
NVIDIA is attempting to bring some of that convenience back to hardware that developers physically control.
The economics are less straightforward
The $4,999 starting price makes the 64GB configuration cheaper than NVIDIA’s higher-memory current offering, but it does not make DGX Spark inexpensive.
There is also an unusual historical comparison.
The original 128GB DGX Spark launched at a considerably lower price than current 128GB configurations. Recent reporting puts NVIDIA’s current 128GB Founders Edition pricing at approximately $6,950, while partner configurations vary. PC Watch
Consequently, the new $4,999 64GB machine should be viewed as a lower current entry point into the platform rather than evidence that local AI hardware broadly became cheaper.
And buying two 64GB machines purely to obtain 128GB of aggregate memory would start at roughly $10,000 before accessories and other costs.
That would be difficult to justify if memory capacity were the buyer’s only requirement.
The argument for two machines is compute scalability.
Two Sparks provide additional processing resources and bandwidth as well as additional memory. Developers expecting workloads to grow incrementally could therefore begin with one machine and add another rather than replacing the original system.
That is a very different purchasing model from a conventional workstation.
Local AI is becoming infrastructure rather than a demo
DGX Spark also illustrates a broader change in local AI.
The first generation of consumer local-LLM experimentation often revolved around a simple question: Can this model run on my GPU?
Developers increasingly want persistent agents that can remain active, process private repositories and documents, use tools and serve applications across multiple devices — part of a broader shift toward AI automation in business.
NVIDIA specifically suggests running coding or research agents continuously on Spark, or using Spark as a dedicated inference machine while applications operate on ordinary laptops and desktops. NVIDIA Blog
That begins to resemble a personal AI server rather than a high-end PC.
The distinction matters because dedicated local inference offers several potential advantages.
Sensitive source code, proprietary documents or internal datasets can remain inside the user’s environment. Developers can experiment without accumulating per-token API charges. Applications can continue operating without relying on an external model endpoint.
Local hardware also provides predictable access to compute.
But none of those advantages eliminates the operational costs of owning hardware: purchase price, electricity, maintenance, software management and eventual obsolescence remain part of the equation.
Cloud infrastructure also has a major advantage when workloads are sporadic. Renting accelerators for occasional experiments can make considerably more financial sense than buying a machine that spends most of its life idle.
DGX Spark therefore makes the strongest case for developers and organizations with sustained local workloads, privacy requirements or a specific need to control the inference environment.
Who should consider the 64GB DGX Spark?
The new model is most compelling for developers whose workloads comfortably fit below the machine’s practical memory limit.
That could include local coding agents, document-analysis systems, retrieval-augmented generation applications, image models, smaller fine-tuning jobs and always-on internal AI services.
A single Spark also provides a relatively clean development environment for software ultimately destined for larger NVIDIA infrastructure.
Teams that already depend heavily on CUDA and NVIDIA’s software ecosystem may therefore find more value in the platform than buyers comparing it purely on hardware specifications.
The 128GB version remains more attractive when large-model experimentation is the primary requirement.
And developers who already know they will routinely exceed 64GB should be cautious about treating clustering as a substitute for buying sufficient memory in the first place. Distributed workloads introduce overhead and are not equivalent to having the same amount of memory inside one system.
What developers should check before buying
The most useful buying criterion is not NVIDIA’s 100-billion-parameter headline.
It is the memory footprint of the workloads you actually intend to run.
Before selecting the 64GB configuration, developers should determine the model’s quantized weight size, expected context length, KV-cache requirements, runtime overhead and whether additional models—such as embedding, vision or reranking models—must operate simultaneously.
Concurrency matters too.
A system comfortably serving one developer may behave very differently when several agents or users make simultaneous requests.
Storage configurations and final pricing will also depend on the manufacturer. NVIDIA’s $4,999 figure is explicitly a starting price. NVIDIA Blog
Anyone considering two Sparks should additionally evaluate whether the target inference framework and model scale efficiently across nodes rather than assuming NVIDIA’s reported 1.7× result will apply to every workload.
The bigger significance of DGX Spark 64GB
The most consequential part of NVIDIA’s announcement is not that DGX Spark now comes with less RAM.
It is that NVIDIA is trying to turn local AI into a scalable computing layer.
One machine handles workloads that fit locally. A second expands memory and compute. Software automates cluster configuration. Model Launcher reduces deployment complexity. Applications running elsewhere on the network consume the resulting AI service.
That architecture resembles a miniature version of the infrastructure used in larger AI deployments.
If the approach works well in practice, developers may increasingly treat desktop AI machines as networked appliances rather than PCs: dedicated boxes that host models and agents for the rest of their devices.
The 64GB DGX Spark is therefore simultaneously more constrained and potentially more accessible than its 128GB sibling.
Its success will depend on whether the rapidly improving efficiency of open models can stay ahead of developers’ appetite for larger models, longer contexts and more ambitious agents.
For now, the practical conclusion is straightforward: 64GB is enough to make serious local AI development possible, but memory planning remains essential.
And NVIDIA’s increasingly polished answer when 64GB is no longer enough is not simply “buy a bigger machine.”
Ingrid Maldine is a business writer, editor and management consultant with extensive experience writing and consulting for both start-ups and long established companies. She has ten years management and leadership experience gained at BSkyB in London and Viva Travel Guides in Quito, Ecuador, giving her a depth of insight into innovation in international business. With an MBA from the University of Hull and many years of experience running her own business consultancy, Ingrid’s background allows her to connect with a diverse range of clients, including cutting edge technology and web-based start-ups but also multinationals in need of assistance. Ingrid has played a defining role in shaping organizational strategy for a wide range of different organizations, including for-profit, NGOs and charities. Ingrid has also served on the Board of Directors for the South American Explorers Club in Quito, Ecuador.