NVIDIA is expanding its desktop AI strategy with a new 64GB version of DGX Spark, positioning the compact Grace Blackwell system as a practical machine for developers who want to run increasingly capable AI models and agents locally rather than depend entirely on cloud infrastructure.
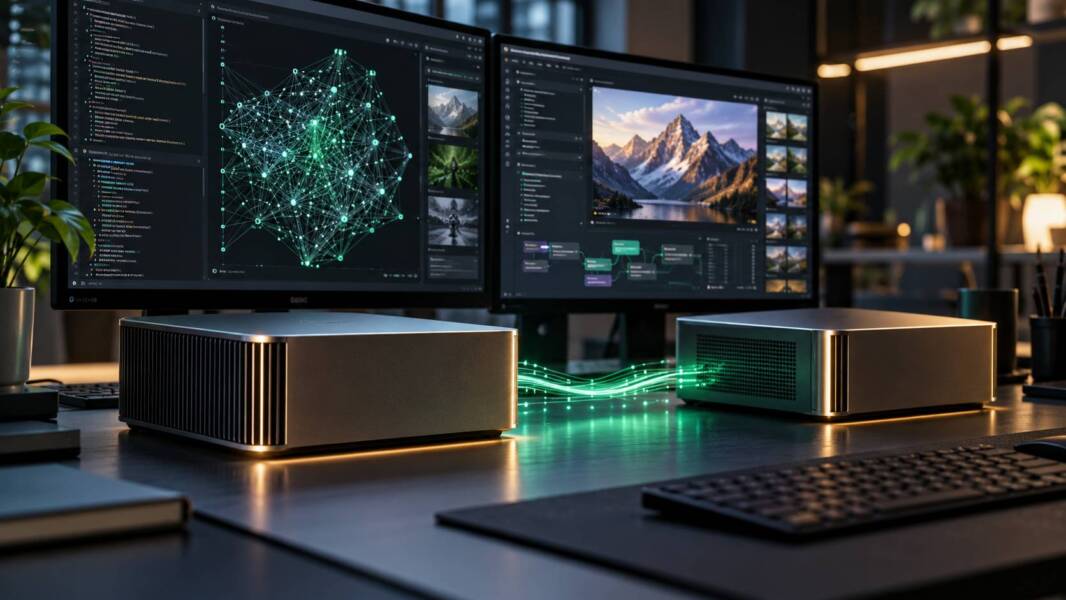
The new configuration will become available on October 23, 2026, through Acer, ASUS, Dell, Gigabyte, HP and MSI, with systems starting at $4,999. It retains the GB10 Grace Blackwell Superchip, DGX OS, NVIDIA’s CUDA-based AI software stack and ConnectX-7 networking found in the larger DGX Spark platform, while reducing unified memory to 64GB. NVIDIA says that is enough to support models with as many as 100 billion parameters on a single system. NVIDIA Blog
But the announcement is more significant than a simple memory configuration.
The arrival of a smaller DGX Spark illustrates a broader change underway in AI computing: powerful open models are becoming efficient enough that serious inference workloads no longer automatically require racks of GPUs or continuously rented cloud accelerators.
At the same time, NVIDIA is trying to make multiple desktop AI computers behave more like a small cluster. Its new NVIDIA Sync Cluster Assistant can connect two DGX Spark systems over high-speed networking, potentially turning local AI infrastructure into something developers can expand incrementally.
That combination — smaller models, unified memory and easier clustering — could make 2026 an important year for local AI development.
There is one major caveat: $4,999 is still expensive for a 64GB machine, and developers should evaluate memory requirements carefully before treating DGX Spark as a replacement for conventional GPU workstations or cloud computing.
What NVIDIA Announced
The new DGX Spark configuration contains 64GB of unified memory shared across its Grace CPU and Blackwell GPU architecture.
The underlying platform remains substantially the same as the existing DGX Spark architecture.
It includes the GB10 Grace Blackwell Superchip, NVIDIA’s DGX OS, CUDA acceleration and ConnectX-7 networking. NVIDIA is positioning the system for inference, AI agents, fine-tuning, data science and edge development. NVIDIA Blog
The 64GB configuration supports widely used AI runtimes and frameworks including Ollama, vLLM and PyTorch with CUDA.
That matters because hardware specifications alone are rarely the biggest obstacle when building local AI systems.
Drivers, inference engines, quantization formats, networking and model deployment can consume considerable engineering time. NVIDIA’s advantage is its attempt to package these components into a preconfigured development platform.
The company describes DGX Spark as a “personal AI supercomputer,” but a more useful way to think about the product is as a small dedicated AI server designed to sit next to a developer’s normal workstation.
Instead of running a large language model directly on a laptop, developers can send inference workloads to DGX Spark while continuing to use their primary computer normally.
64GB Is More Useful Than It Sounds
The headline reduction from 128GB to 64GB might initially appear severe.
For many local AI workloads, however, 64GB is increasingly viable.
Model quantization and more efficient architectures have dramatically reduced the memory needed to run capable open-weight models.
NVIDIA says the 64GB DGX Spark can support models containing up to 100 billion parameters. That figure should not be interpreted as meaning every 100-billion-parameter model will run comfortably under every configuration.
Actual memory consumption depends on several factors, including quantization, context length, key-value cache requirements, inference framework and concurrent users.
A model using 4-bit weights, for example, requires far less memory than the same model running at higher numerical precision.
Long context windows can also consume substantial additional memory.
This means developers should not purchase hardware based solely on parameter counts.
The more useful question is:
How much memory does the actual model and workload require?
For developers running 20B–40B-class models, coding assistants, document-analysis systems or specialized agents, 64GB can provide considerably more flexibility than conventional consumer GPUs.
That is particularly important because unified-memory architectures remove one of the traditional constraints of desktop AI: GPU VRAM.
Why Unified Memory Matters for Local AI
Traditional workstation architectures separate system RAM from GPU memory.
A computer might have 128GB of system RAM but only 24GB or 32GB of GPU memory. Large models therefore cannot necessarily use all of the computer’s available memory efficiently.
DGX Spark takes a different approach.
Its CPU and GPU share a unified memory pool.
That architecture allows workloads larger than typical consumer GPU VRAM limits to remain available to the accelerator without the same CPU-to-GPU memory boundary found in conventional PCs.
Unified memory does not magically make every workload faster.
Memory bandwidth, compute throughput, quantization and software optimization remain critical.
But for large-model inference, capacity itself can determine whether a model runs at all.
That makes 64GB unified memory considerably more interesting for AI development than 64GB of conventional system RAM.
NVIDIA Wants Developers to Cluster Their Desktops
The second important part of NVIDIA’s announcement is not the new memory configuration.
It is NVIDIA Sync.
Every DGX Spark includes ConnectX-7 networking. Two machines can be directly connected and configured as a small multi-node AI cluster.
According to NVIDIA, two 64GB systems can pool memory to provide 128GB for workloads and expand model support to as much as 200 billion parameters. NVIDIA Blog
NVIDIA Sync Cluster Assistant handles much of the configuration automatically by discovering systems, validating their setup and configuring the ConnectX-7 network.
This addresses a surprisingly important problem.
Distributed AI infrastructure is powerful, but historically it has not been particularly convenient.
Configuring networking, distributed inference frameworks and model partitioning can turn what sounds like a simple two-machine deployment into a substantial engineering project.
NVIDIA is trying to abstract that complexity.
If the approach works reliably, developers could start with one DGX Spark and add another system later rather than purchasing significantly larger infrastructure upfront.
Two Machines Do Not Mean Twice the Performance
There is an important distinction between memory scaling and compute scaling.
Connecting two 64GB DGX Spark systems gives developers access to a larger combined memory pool, but distributed workloads introduce communication overhead.
NVIDIA reports that two 64GB systems running its Qwen 3.8 27B test delivered up to 1.7 times the performance of a single system. NVIDIA Blog
That is NVIDIA’s own benchmark rather than an independent result, and performance will vary considerably by model and workload.
Still, the figure illustrates an important principle.
Two machines may provide twice the aggregate hardware resources without delivering exactly twice the application performance.
The value of clustering may therefore be memory capacity rather than raw speed.
For some developers, simply being able to load a model that cannot fit on one machine is more important than maximizing tokens per second.
The Real Opportunity: Always-On Local AI Agents
NVIDIA is emphasizing AI agents as one of DGX Spark’s primary workloads.
That makes sense.
Traditional chatbot usage is intermittent. A user sends a prompt, the model produces an answer and the interaction ends.
Agents behave differently.
They may continuously monitor information, call tools, inspect files, write code, run tests, perform searches and repeat operations.
An agent operating throughout the day can therefore generate a large amount of inference activity.
Cloud APIs are convenient for these workloads, but continuous inference creates ongoing usage costs.
Local hardware changes the economic model.
The developer pays a substantial upfront cost for the machine but does not pay a provider for every generated token.
That does not automatically make local inference cheaper. Electricity, hardware depreciation, maintenance and engineering time still matter.
But workloads that run continuously are exactly where local infrastructure becomes more economically interesting.
Privacy Is Another Important Advantage
Cost is only one reason developers might run AI locally.
Data control may be more important.
Organizations increasingly want AI systems to analyze source code, internal documents, engineering specifications and proprietary datasets.
Sending that information to an external API introduces governance questions even when the provider offers strong enterprise privacy guarantees.
Local inference changes the architecture.
Sensitive information can remain inside the organization’s own infrastructure.
NVIDIA explicitly highlights the ability to run models and agents on DGX Spark without cloud dependency. NVIDIA Blog
For regulated industries, research organizations and companies handling valuable intellectual property, that could be one of the platform’s strongest selling points.
The $4,999 Question
The new configuration starts at $4,999.
That price complicates the story.
This is not an inexpensive desktop designed to democratize AI computing for ordinary PC users.
It is professional development hardware.
Independent coverage has also highlighted the unusual pricing environment surrounding the launch. Tom’s Hardware notes that current 128GB DGX Spark systems can cost substantially more, while more efficient models have made 64GB increasingly practical for local inference. Tom’s Hardware
The relevant comparison is therefore not simply:
DGX Spark versus a normal desktop PC.
Potential buyers should compare at least three approaches:
- A DGX Spark or similar unified-memory AI system.
- A conventional workstation containing one or more discrete GPUs.
- Cloud GPU or API usage.
Each model has different economics.
Cloud infrastructure provides nearly unlimited scalability without upfront hardware costs.
GPU workstations can provide excellent performance while remaining useful for conventional graphics and compute workloads.
DGX Spark prioritizes large unified memory, NVIDIA’s AI software environment and compact deployment.
The right choice depends heavily on workload utilization.
A machine sitting idle most of the day can be difficult to justify against cloud services.
A machine running inference continuously may produce a very different calculation.
Local AI Is Becoming Its Own Hardware Category
Perhaps the most interesting part of DGX Spark is what it suggests about the evolution of personal computing.
For decades, desktop computers were largely general-purpose machines.
AI is creating a new category: dedicated local inference infrastructure.
These systems do not necessarily replace laptops or workstations.
They operate alongside them.
A developer might write code on a MacBook or Windows workstation while a dedicated AI appliance continuously runs models elsewhere on the local network.
Creative professionals could similarly offload image generation or video processing.
Researchers could maintain persistent models without reserving cloud instances.
Small companies could operate internal assistants that remain available around the clock.
This architecture begins to resemble the relationship between personal computers and network-attached storage.
A NAS separates storage from the computer being used.
A local AI server separates inference from the computer being used.
DGX Spark is one of the clearest attempts yet to commercialize that idea.
Smaller Models Are Changing the Hardware Equation
None of this would matter if useful AI models continued growing indefinitely.
Instead, model development is moving in two directions simultaneously.
Frontier models continue becoming larger and more computationally demanding.
But smaller models are becoming dramatically more capable.
Improved training techniques, distillation, mixture-of-experts architectures and quantization are increasing the intelligence available per gigabyte of memory.
NVIDIA itself explicitly points to increasingly capable open models shrinking enough to fit on more local devices. NVIDIA Blog
That trend could ultimately matter more than any individual piece of hardware.
If a model requiring 128GB today can achieve similar practical performance in 64GB tomorrow, the useful life of local AI hardware expands.
Hardware requirements would no longer necessarily grow at the same pace as model capabilities.
What Developers Should Evaluate Before Buying
The new DGX Spark should not be evaluated from the specification sheet alone.
Prospective buyers should benchmark their actual workloads whenever possible.
The most important variables include model size and quantization, context length, expected concurrency, inference speed requirements, software compatibility and whether workloads need to run continuously.
Memory headroom deserves particular attention.
Running a model that barely fits into available memory leaves little capacity for larger context windows, additional agents or future models.
Developers considering the 64GB system should therefore determine whether their expected workloads comfortably fit within that envelope rather than merely confirming that they can technically run.
Clustering should also be viewed as an expansion strategy rather than an excuse to undersize the first system.
Two $4,999 machines represent roughly $10,000 of hardware before other costs.
At that level, alternative workstation and server configurations deserve serious comparison.
Why This Announcement Matters
DGX Spark 64GB is not revolutionary because NVIDIA removed half the memory from an existing platform.
The important development is the architecture NVIDIA is trying to establish around it.
A developer can theoretically start with one compact local AI machine, run models privately, connect applications from other computers and later add additional nodes as workloads grow.
NVIDIA Sync attempts to make that expansion progressively easier.
If local AI continues moving toward persistent agents rather than occasional chatbot queries, that architecture becomes increasingly logical.
The cloud will remain essential for training frontier models and handling workloads that require rapid elastic scaling.
But inference does not necessarily need to follow the same architecture as training.
A substantial amount of AI computation may eventually happen on hardware owned by the people and companies using the models.
The new DGX Spark is another indication that NVIDIA expects that market to become significant.
And as efficient open models improve, the key question for developers may gradually shift from “Can I run this model locally?” to “Does it still make sense to pay someone else to run it for me?”
Ingrid Maldine is a business writer, editor and management consultant with extensive experience writing and consulting for both start-ups and long established companies. She has ten years management and leadership experience gained at BSkyB in London and Viva Travel Guides in Quito, Ecuador, giving her a depth of insight into innovation in international business. With an MBA from the University of Hull and many years of experience running her own business consultancy, Ingrid’s background allows her to connect with a diverse range of clients, including cutting edge technology and web-based start-ups but also multinationals in need of assistance. Ingrid has played a defining role in shaping organizational strategy for a wide range of different organizations, including for-profit, NGOs and charities. Ingrid has also served on the Board of Directors for the South American Explorers Club in Quito, Ecuador.