The Nvidia Vera CPU is emerging as an important development in artificial intelligence infrastructure, as businesses seek more efficient ways to run autonomous AI agents. Following new performance tests announced by Modal on October 19, 2026, the processor could help reshape how companies evaluate computing performance, infrastructure costs, and enterprise AI investments.
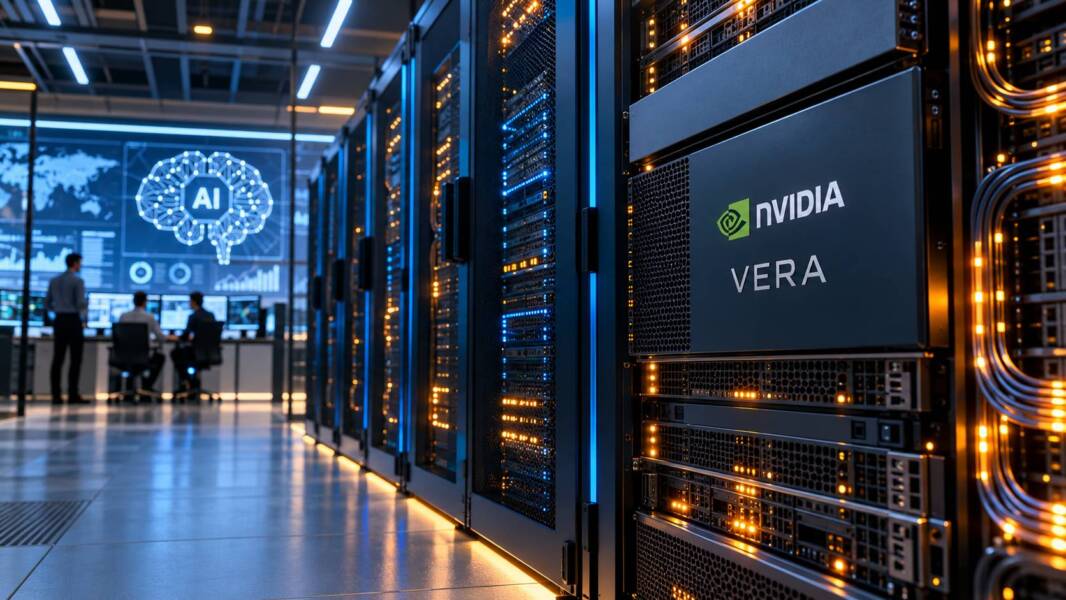
On October 19, 2026, AI cloud infrastructure company Modal announced plans to support the new Vera CPU developed by Nvidia, following early performance tests showing up to twice the task throughput of a comparable x86 server under demanding workloads.
The announcement represents an important step in Nvidia’s strategy to expand beyond the graphics processing units that have powered much of the generative AI revolution.
For businesses investing in artificial intelligence, however, the more significant lesson is about infrastructure economics.
As AI applications evolve from answering questions to completing complex assignments, the ability to execute thousands of simultaneous tasks efficiently is becoming increasingly important.
Companies may soon discover that improving the underlying computing infrastructure delivers substantial benefits without requiring a more powerful AI model.
The central question is shifting from how quickly an AI system generates an answer to how efficiently it completes useful work. Modal
Nvidia’s Latest Expansion Beyond GPUs
Nvidia has become one of the defining companies of the AI era because its graphics processors are particularly effective at the parallel mathematical operations required to train and operate large artificial intelligence models.
But GPUs are only one part of the infrastructure supporting modern AI applications.
An autonomous AI agent might use a language model to decide what to do next, but completing its assignment often requires additional operations.
It may need to search databases, execute Python code, install software packages, inspect files, interact with external applications, or evaluate the results of previous actions.
Many of these activities depend heavily on CPUs rather than GPUs.
This creates an opportunity for Nvidia to supply a greater proportion of the computing infrastructure required by AI developers.
Its Vera processor, introduced in May 2026, was designed specifically for demanding AI-related workloads.
According to Nvidia’s original announcement, Vera features 88 custom Olympus CPU cores and a high-bandwidth memory subsystem capable of delivering up to 1.2 terabytes per second.
The processor can operate independently or as part of Nvidia’s broader Vera Rubin computing platform.
Nvidia has positioned the technology for applications including autonomous AI agents, reinforcement learning, data processing, and large-scale computing environments. NVIDIA Investor Relations
The commercial implications are significant.
Instead of selling primarily the accelerators used to run AI models, Nvidia can increasingly compete to supply the processors responsible for coordinating and executing the work surrounding those models.
That broadens its potential role in corporate computing infrastructure.
Why Modal’s Decision Matters
Modal provides cloud infrastructure that allows developers to build, deploy, and operate AI applications without managing much of the underlying hardware themselves.
The Nvidia Vera CPU gives Modal another hardware option as demand for AI agent execution continues to grow.
Its services support activities ranging from model inference and training to the execution of autonomous software agents.
The company has expanded rapidly.
On October 14, Modal announced that it had exceeded $1 billion in annualized revenue run rate and raised $750 million in Series D financing at a $15.75 billion post-money valuation.
According to the company’s announcement, usage had tripled over the preceding five months, while revenue had increased more than fifteenfold year over year.
Modal also reported that its sandbox product, which provides isolated environments for executing code, had reached an annualized revenue run rate of approximately $300 million.
These figures are company-reported operating metrics, not audited full-year revenue.
Nevertheless, they illustrate the growing commercial demand for infrastructure designed around AI applications. Modal
Modal’s decision to introduce Vera is particularly relevant because its existing CPU infrastructure had relied on processors from Intel and AMD.
Adding Nvidia creates another option for allocating computing workloads.
Importantly, Modal is not abandoning its established suppliers.
Chief Executive Erik Bernhardsson told Reuters that the company intends to maintain a mixed hardware environment, allowing workloads to run on whichever architecture delivers the strongest performance.
That approach reflects an increasingly important principle for AI infrastructure buyers: flexibility can be more valuable than committing exclusively to a single technology provider. Euronext Live
What the Performance Tests Actually Showed
The most striking result in Modal’s October 19 announcement was a reported improvement of up to two times in task throughput.
The Nvidia Vera CPU demonstrated its strongest advantage when multiple agent workloads competed for computing resources.
But understanding the conditions behind that result is essential.
Modal developed a benchmark designed to simulate the types of computing operations performed by autonomous AI agents.
The test incorporated 50 tasks derived from Terminal-Bench, including software compilation, file searches, Git operations, and other activities commonly encountered when agents execute code.
The benchmark deliberately removed network activity and language-model waiting time to isolate CPU-related performance.
Modal also published the benchmark implementation, allowing technical teams to inspect the methodology. GitHub
The difference between latency and throughput
Two performance measurements are especially important.
Latency measures how long an individual task takes to complete.
Throughput measures how many tasks a system can complete within a given period.
A processor might execute one task only slightly faster than a competitor while handling substantially more simultaneous tasks.
That distinction matters because AI infrastructure frequently operates under conditions of high concurrency.
Modal’s engineers reported that Vera’s advantage was most pronounced when many tasks competed for computing resources.
Under lighter workloads, Vera did not consistently outperform every alternative by a large margin.
However, as the number of simultaneous workloads increased, its performance became more differentiated.
In early testing, Modal reported up to twice the throughput of a comparable Intel Granite Rapids x86 machine, without a corresponding deterioration in individual task latency.
The company attributed much of the advantage to Vera’s ability to handle memory-intensive workloads under contention. Modal
What the benchmark does not establish
The results are promising, but they should not be interpreted as proof that Vera will double the performance of every AI application.
Several limitations matter.
First, the tests were conducted by a prospective customer evaluating the hardware, rather than through an independently verified industry-wide study.
Second, the benchmark deliberately excluded the time required for language-model inference and network communication.
Third, the results reflect specific hardware configurations and workloads.
Finally, Modal acknowledged that newer processors from competing suppliers could narrow the performance gap.
Consequently, the evidence supports a narrower conclusion: Vera demonstrated a substantial throughput advantage in Modal’s early tests of particular concurrent, CPU-intensive agent workloads.
Whether those gains translate into lower operating costs across diverse production environments remains to be established.
The Business Opportunity: Lower Cost per Completed Task
The commercial significance of the results becomes clearer when AI infrastructure is evaluated through business outcomes rather than hardware specifications.
For enterprise customers, the Nvidia Vera CPU raises an important question: can greater throughput translate into a lower cost per completed task?
Traditional computing procurement often emphasizes processor speed, core counts, memory capacity, or hourly rental prices.
Those measurements remain relevant, but they do not necessarily reveal the cost of delivering a useful result.
For an AI agent, the more meaningful metric may be the total expense required to complete a task successfully.
Consider a hypothetical company operating an AI service that processes customer documentation.
Its infrastructure performs thousands of operations involving file extraction, database searches, document classification, and automated validation.
Suppose its existing servers complete 1,000 tasks per hour at an infrastructure cost of $100 per hour.
The infrastructure cost per completed task would be $0.10.
Now imagine an alternative configuration completes 1,800 comparable tasks per hour at a cost of $120 per hour.
Its cost per completed task would fall to approximately $0.067.
That represents a reduction of roughly 33%.
These figures are illustrative, not actual pricing or performance measurements for Nvidia Vera.
They demonstrate why a more expensive server can still be economically attractive if it produces sufficiently greater useful throughput.
For businesses deploying AI at scale, the relevant question is not simply whether new hardware is faster.
It is whether the total cost of completing a reliable, successful task decreases.
Why AI Agents Change Infrastructure Requirements
The rise of autonomous AI agents is creating computing patterns that differ from those associated with traditional enterprise applications.
The Nvidia Vera CPU was designed with demanding AI workloads in mind, including the execution patterns associated with autonomous agents.
A conventional business application generally follows relatively predictable workflows.
An AI agent may behave differently.
It can receive an objective, determine a sequence of actions, execute code, evaluate intermediate results, and repeat the process until the assignment is complete.
The computing resources required may fluctuate substantially throughout that sequence.
For example, an AI coding assistant might spend several seconds waiting for a language model before suddenly consuming significant CPU capacity while compiling software or running tests.
When thousands of agents operate simultaneously, these unpredictable bursts create substantial infrastructure-management challenges.
Modal describes this problem as resource contention between workloads sharing the same computing environment.
One agent’s sudden demand for processing capacity can affect the performance of other agents running on the same server.
Infrastructure providers must therefore balance resource utilization against reliability and responsiveness. Modal
The hidden cost of idle GPUs
There is another economic consideration.
Some AI training and evaluation systems depend on a sequence of operations involving both GPUs and CPUs.
A GPU may generate model outputs that subsequently need to be evaluated through CPU-based software execution.
If those evaluations take too long, expensive GPU resources can remain underutilized while waiting for the next stage of processing.
Reducing CPU bottlenecks can therefore improve the utilization of other infrastructure components.
This is an important distinction.
A faster CPU does not necessarily make an AI model more intelligent.
But it may allow the overall system to produce more useful work with the same amount of expensive accelerator capacity.
For companies operating large AI systems, these efficiency improvements can have meaningful financial consequences.
Nvidia’s Strategy Creates New Competitive Pressure
Nvidia’s expansion into CPUs also changes the competitive landscape for semiconductor manufacturers.
The Nvidia Vera CPU also expands the company’s competitive position in a server market traditionally dominated by Intel and AMD.
Intel and AMD have traditionally occupied central positions in the server processor market.
Both companies continue developing increasingly advanced products for enterprise and data-center customers.
Nvidia’s entry introduces another major competitor, particularly in environments designed specifically for AI.
The company also benefits from an established position in GPU computing.
Customers building AI infrastructure may find advantages in purchasing tightly integrated computing components from the same supplier.
Potential benefits include simpler system integration, coordinated hardware development, and optimized communication between processors.
However, deeper integration can create trade-offs.
A business that depends heavily on one hardware ecosystem may face higher switching costs or reduced flexibility when evaluating competing technologies.
This makes Modal’s mixed-fleet strategy noteworthy.
Rather than treating the adoption of Vera as a permanent commitment to one processor architecture, the company intends to compare alternatives and assign workloads accordingly.
For enterprise buyers, this is a practical model worth considering.
The objective should be to maintain competitive options while optimizing performance, reliability, and total cost.
The Challenge of Moving Beyond x86
Adopting Vera is not necessarily a straightforward hardware replacement.
Adopting the Nvidia Vera CPU requires businesses to consider Arm compatibility alongside potential performance improvements.
Vera uses an Arm-compatible architecture, while much of the established enterprise server ecosystem has historically relied on x86 processors.
That distinction creates software compatibility considerations.
Applications, dependencies, container images, development tools, and operating environments may need to support the new architecture.
Modal acknowledged that introducing Arm support would require changes to its infrastructure and image-building systems. Modal
For other organizations, migration costs could include:
- Rebuilding or validating software dependencies.
- Testing application compatibility.
- Updating deployment pipelines.
- Evaluating monitoring and security tools.
- Training infrastructure teams.
- Maintaining parallel environments during the transition.
These costs should be incorporated into financial evaluations.
A processor that delivers stronger benchmark results may not produce an immediate return on investment if migration expenses are substantial.
The appropriate decision depends on workload characteristics, deployment scale, and the expected operating life of the infrastructure.
What Business Leaders Should Evaluate Before Investing
The broader lesson from Modal’s announcement is that AI infrastructure purchasing should increasingly focus on measurable business outcomes.
Although the Nvidia Vera CPU shows promising early results, procurement decisions should be based on independently validated workload performance and total cost.
Organizations do not need to operate enormous data centers to apply this principle.
The same framework is useful when choosing cloud providers, enterprise AI platforms, or managed automation services.
1. Measure completed work, not only computing speed
Executives should ask technology teams to establish performance metrics connected to business value.
These might include successfully completed customer requests, resolved support cases, processed invoices, or validated software changes.
A system that produces more operations per second is not necessarily more valuable if those operations do not improve business outcomes.
2. Calculate the complete cost of AI execution
Infrastructure costs extend beyond processor rental.
They can include model inference, storage, networking, software licensing, monitoring, security, and engineering support.
For autonomous agents, failed tasks and repeated attempts may also increase costs.
A useful evaluation therefore measures total expenditure against successful outcomes.
3. Test systems under realistic demand
Hardware comparisons conducted under ideal conditions can conceal performance problems that emerge in production.
Businesses should test their AI systems during periods of high concurrency and unpredictable demand.
Average response time alone may be insufficient.
The slowest portion of user requests can be particularly important for customer-facing services.
4. Maintain flexibility between providers
Technology markets evolve quickly.
Today’s strongest-performing processor may not remain the best choice for every workload.
Organizations should consider whether their software architecture allows workloads to move between providers without excessive redevelopment.
5. Include reliability and security
Performance improvements should not come at the expense of operational controls.
AI agents may execute code, access sensitive information, or interact with critical business systems.
Isolation, access permissions, auditability, and failure recovery remain essential.
A faster system that introduces unacceptable operational risk is not necessarily a better investment.
What This Development Means for Entrepreneurs
Startups building AI products face a particularly interesting opportunity.
In earlier phases of the generative AI market, competition frequently centered on access to powerful models.
Model quality remains important, but the infrastructure required to turn model outputs into reliable services is becoming another area of differentiation.
An entrepreneur building an AI research assistant, automated accounting platform, or software development service must consider more than the model generating responses.
The product also needs infrastructure capable of executing tasks, coordinating workflows, and managing unpredictable demand.
Better infrastructure can potentially improve response times, reduce operating expenses, and make new business models financially viable.
This creates opportunities for companies specializing in orchestration, workload scheduling, secure execution environments, and infrastructure optimization.
It also creates challenges.
As underlying computing becomes more efficient, some technical capabilities may become easier for competitors to reproduce.
Sustainable differentiation may increasingly depend on proprietary workflows, customer relationships, trusted data access, and measurable business results.
For entrepreneurs, infrastructure efficiency is therefore both a cost-management issue and a strategic consideration.
The Bigger Picture: AI Spending Faces Greater Scrutiny
The timing of Nvidia’s latest customer announcement is significant.
Artificial intelligence infrastructure has attracted extraordinary investment, but investors are increasingly questioning how quickly that spending will translate into sustainable profits.
During October, concerns about financing costs and the scale of AI-related capital expenditure contributed to volatility in semiconductor and infrastructure stocks.
On October 19, Reuters reported a rebound in several AI-related companies following a difficult period for the sector.
Nevertheless, questions surrounding debt, infrastructure utilization, and returns on investment remain important. Reuters
This environment increases the commercial importance of technologies that can improve computing efficiency.
If infrastructure providers can complete more work using the same physical capacity, they may be able to improve margins or offer more competitive prices.
But higher throughput alone does not guarantee profitability.
Demand, hardware acquisition costs, electricity prices, financing expenses, depreciation, and competitive pricing all influence financial outcomes.
The market will ultimately need evidence that technical performance improvements translate into sustainable economic returns.
What Happens Next?
Several developments will determine whether Vera becomes a major competitor in enterprise computing.
The long-term success of the Nvidia Vera CPU will depend on production performance, competitive pricing, software compatibility, and enterprise adoption.
The first is broader production adoption.
Early benchmarks provide useful evidence, but real-world deployments across different customers and workloads will offer a more complete assessment.
The second is pricing.
Customers will need to compare the total cost of Vera-based systems against alternatives from Intel, AMD, and other Arm-based suppliers.
The third is software compatibility.
The easier it becomes to deploy existing applications on Arm-based infrastructure, the larger the potential market.
The fourth is competitive response.
Intel and AMD are continuing to develop new server processors, and future comparisons may produce different results.
Finally, enterprise demand for autonomous AI agents will influence how rapidly the market expands.
If agents become central to everyday business operations, infrastructure optimized for large numbers of concurrent tasks could become increasingly valuable.
If adoption develops more slowly, the commercial opportunity may take longer to materialize.
The Bottom Line
Modal’s decision to introduce Nvidia Vera CPUs is more than another semiconductor customer announcement.
It offers a useful illustration of how the economics of artificial intelligence are evolving.
As companies deploy increasingly sophisticated AI agents, performance will depend not only on the intelligence of the underlying models but also on the efficiency of the infrastructure executing their instructions.
The strongest competitive advantage may come from systems that coordinate models, processors, memory, and software more effectively.
For business leaders, the practical takeaway is straightforward:
Evaluate AI investments according to the cost, reliability, and speed of completed business outcomes—not simply the specifications of the underlying technology.
Nvidia’s latest expansion demonstrates why that distinction is becoming increasingly important.
Ingrid Maldine is a business writer, editor and management consultant with extensive experience writing and consulting for both start-ups and long established companies. She has ten years management and leadership experience gained at BSkyB in London and Viva Travel Guides in Quito, Ecuador, giving her a depth of insight into innovation in international business. With an MBA from the University of Hull and many years of experience running her own business consultancy, Ingrid’s background allows her to connect with a diverse range of clients, including cutting edge technology and web-based start-ups but also multinationals in need of assistance. Ingrid has played a defining role in shaping organizational strategy for a wide range of different organizations, including for-profit, NGOs and charities. Ingrid has also served on the Board of Directors for the South American Explorers Club in Quito, Ecuador.