Oracle announced a set of cloud-networking changes on October 27 that target a problem increasingly important to artificial intelligence: expensive accelerators can spend time waiting for data, and a single congested or failed connection can slow an entire distributed workload. The update extends remote direct memory access (RDMA) to Oracle Cloud Infrastructure’s front-end network, introduces a congestion-aware collective-communication plugin for AI clusters, expands NVMe block-storage attachment options and adds transparent multipath capabilities.
The practical promise of Oracle Acceleron networking is not simply faster links. It is better use of existing compute capacity through more predictable data movement and recovery from failures. Oracle says its expanded NVMe block-storage attachment options can improve performance by up to three times, but it has not published enough workload-level data in the announcement to treat that figure as a universal gain. Nor has it established that all the newly described capabilities are immediately available on every OCI instance type. Oracle’s October 27 announcement describes the feature set and includes a forward-looking product disclaimer.
Oracle
For cloud architects, machine-learning engineers and infrastructure teams, the more useful question is what each mechanism solves—and which measurements would show whether it helps a particular application.
Why AI Clusters Are Increasingly Limited by Networking
Modern AI infrastructure is a coordinated system of processors, memory, storage, network adapters, switches and software. Adding GPUs increases theoretical compute capacity, but a training job often needs many devices to exchange gradients, model parameters or other intermediate results before the next step can proceed. When one part of that communication runs slowly, faster devices may wait.
Inference has different traffic patterns, but networking can still be critical. Distributed inference may move model states among machines; retrieval-augmented applications fetch data from external stores; and agents execute tools that involve databases, storage and other services. Performance depends on the complete path from data source to useful output, not only the accelerator’s peak arithmetic throughput.
This is why the infrastructure discussion increasingly extends beyond GPUs. TechnologyHQ recently examined why CPU performance matters for AI agents, and its coverage of Scaleway’s planned AMD-based AI supercomputer in Sweden showed how storage, interconnects and software shape an accelerator cluster’s practical value. Oracle’s latest work addresses another piece of the same engineering problem: how data travels reliably under load.
The difference between bandwidth, latency and job completion time
Bandwidth measures how much data a connection can carry per second. Latency measures the delay before a transfer makes progress or reaches its destination. Tail latency captures unusually slow operations, which can dominate synchronized jobs even when average performance looks healthy. Job completion time includes all of these factors plus compute, storage and software overhead.
A network upgrade might improve peak bandwidth without materially shortening a job if the workload is compute-bound. Conversely, reducing congestion or recovering from a failed path can save an entire training run from a lengthy restart. Infrastructure buyers should measure the latter outcomes rather than assume every advertised network improvement translates directly into lower model-training cost.
How Oracle Acceleron Networking Brings RDMA to the Front End
Remote direct memory access lets one machine transfer data to or from another machine’s memory with relatively little involvement from the remote CPU and conventional operating-system networking stack. That can reduce overhead and latency for high-throughput applications. RDMA is familiar in high-performance computing and AI back-end fabrics, but Oracle’s new High-Performance Fabric brings it to OCI’s shared front-end compute network, which also carries a much wider mix of services and customer traffic.
The distinction matters for Oracle Acceleron networking. A dedicated GPU back-end fabric can be engineered around relatively predictable communication patterns. A front-end network may carry database queries, object and block-storage traffic, short application requests, large transfers and connections to other networks. Those flows compete for shared resources and respond differently to congestion.
According to an October 27 technical explanation by OCI engineers, Oracle uses its Acceleron SmartNICs to manage those competing requirements. The company’s design aims to support RDMA alongside ordinary network traffic while preserving throughput, latency and workload isolation. These are vendor-described architectural properties, not independent proof that every workload experiences the same results.
cloud-infrastructure
Why RDMA needs more careful congestion control
RDMA is sensitive to packet loss and congestion. Simply enabling it on a busy shared network can create unpredictable behavior if large transfers compete with latency-sensitive services. Traditional TCP traffic generally adjusts its sending behavior through window-based congestion control, while RDMA commonly uses rate-based approaches. Their interactions can produce unfairness if the network does not coordinate them.
Oracle says its SmartNICs use hierarchical token buckets to track bandwidth consumption across RDMA and non-RDMA classes. A shared parent bucket represents available capacity; child buckets represent traffic classes. When a class consumes more of its allowance, the SmartNIC can signal congestion by marking ECN-capable packets or dropping packets that cannot respond to explicit congestion notification. The scheme is designed to let one class borrow unused capacity from another instead of reserving bandwidth that sits idle.
This is especially relevant during incast, when many senders transmit toward the same destination at once. Without effective congestion signals, queues can build rapidly and delay unrelated work. Oracle describes signaling congestion before those queues become excessive. The design offers a concrete engineering mechanism, although customers still need workload-specific measurements to assess its benefits.
One-way delay and alternate-path selection
For congestion inside the network fabric, Oracle describes a one-way-delay congestion-control mechanism in its SmartNICs. Measuring delay in the forward direction helps distinguish a genuinely congested outbound path from a slow return path that might distort round-trip measurements. When the adapter detects elevated delay, Oracle says it probes three alternate paths and moves the flow if a better route exists; otherwise it signals congestion.
That approach is more adaptive than treating every available path as equally healthy. It also adds implementation questions: how quickly can congestion be detected, how often do flows move, and does path switching affect application tail latency? Those are useful subjects for an OCI proof of concept.
Oracle Acceleron Networking and the Collective-Communication Bottleneck
Oracle’s second major change is the Oracle Collective Communications Library plugin, or OCCL. Collective-communication libraries coordinate operations such as all-reduce, all-gather and broadcast across distributed accelerators. These operations are essential in many training systems because participating devices must exchange data in coordinated phases.
Conventional equal-cost multipath forwarding can spread flows across several routes, but it often makes decisions without knowing how large each flow will be. Some paths become overloaded while others have spare capacity. In a synchronized workload, the slowest transfer can delay the next computation step.
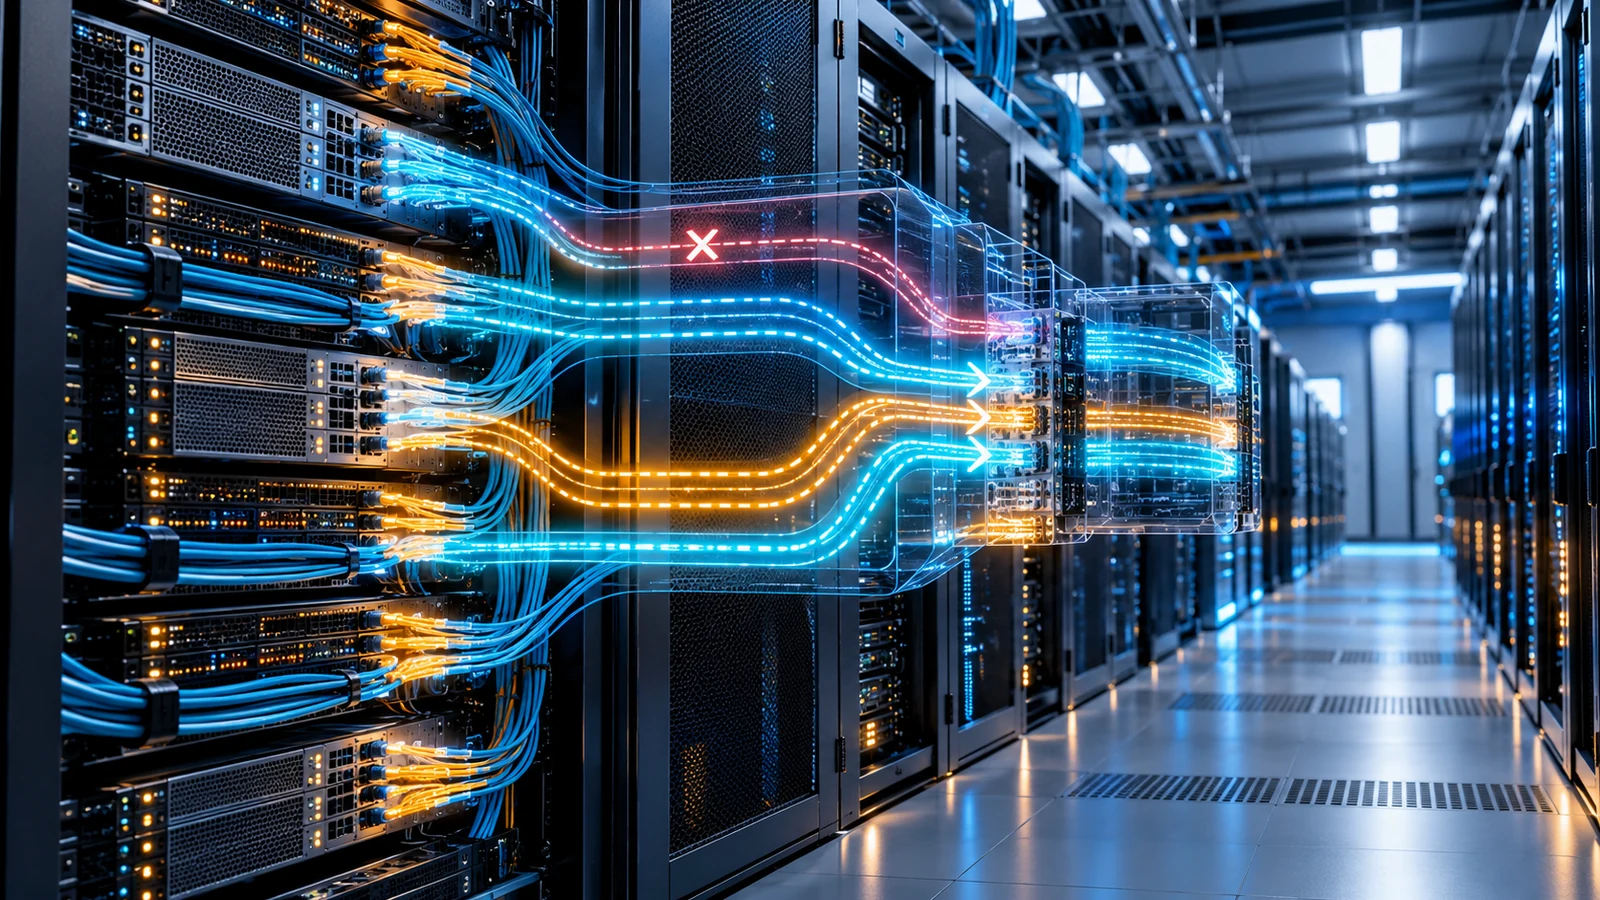
OCCL attempts to address this at the collective-communication layer. Oracle says the plugin distributes traffic across multiple RDMA queue pairs, favors paths delivering better throughput and moves messages or chunks away from congested or failed paths. It works through a standard collective-communication-library network-plugin interface, rather than requiring the application to manage every physical network route. The OCI engineering post describes both message-level and chunk-level load balancing.
cloud-infrastructure
What multipath failover actually protects
Oracle’s multiplanar network design provides more than one path through the infrastructure. OCCL is intended to detect port or NIC failures and redirect collective traffic to another available route so a distributed job can continue without restarting because of that network failure. Oracle also announced transparent front-end multiplanar networking, with automatic path selection, failover and congestion control for front-end RDMA traffic.
These are meaningful resilience mechanisms, but their scope should be understood precisely. Network failover does not prevent failures caused by a GPU, host process, application bug, storage service or power event. Nor does the announcement guarantee zero interruption or zero packet loss under every fault. An application may still have its own timeout and recovery behavior.
For Oracle Acceleron networking, a good validation exercise deliberately disables a network link or adapter during a representative distributed workload, then records recovery time, errors, lost work and total job completion time. The strongest result would be a completed job with a measured, acceptable slowdown—not merely a successful failover demonstration in an idle test environment.
What the Claimed 3× NVMe Performance Gain Means
Oracle also announced expanded NVMe block-storage attachment options across Acceleron bare-metal and virtual-machine shapes, with a company-reported performance improvement of up to 3×. NVMe is a storage interface designed for low-latency, parallel access; in cloud environments, the end-to-end performance also depends on the network, host path, storage service and workload.
The announcement does not identify a universal baseline, block size, queue depth, read/write mix or latency percentile for the threefold figure. It should therefore be presented as an upper-bound vendor claim for certain configurations, not as a statement that all OCI storage will become three times faster. The right test uses the same instance class, volume configuration and representative I/O pattern before and after a supported change.
For AI systems, storage performance matters when loading large checkpoints, streaming datasets or recovering a training job. But the application may be limited by decompression, preprocessing, CPU work or network collectives instead. Measuring storage IOPS in isolation is useful, yet the decisive metric is whether the complete workload finishes sooner or meets its latency target more consistently.
Why Oracle Acceleron Networking Matters for Multi-Tenant Clouds
Cloud providers face a harder problem than operators of a single-purpose AI cluster: they must deliver predictable performance while keeping unrelated customers and workloads isolated. Oracle positions Acceleron as a combination of dedicated fabrics, programmable networking, converged NIC functionality and host-level zero-trust routing. Its October 27 announcement describes security and multi-tenant resilience as central design goals, though the newly enumerated feature details focus mainly on RDMA, storage and failover.
The technical issue is that performance isolation and security isolation are not identical. A tenant can be prevented from accessing another tenant’s data while still experiencing noisy-neighbor contention on shared links. Conversely, a fast dedicated path is not a substitute for authorization, encryption, monitoring or segmentation. Infrastructure teams need evidence for both dimensions.
Oracle’s architecture is particularly relevant to organizations that combine training, inference, databases and application services within the same cloud environment. It suggests a way to use a common front-end network for a wider range of high-performance tasks without requiring every workload to operate on a separate specialized fabric. Whether that simplifies a particular deployment depends on instance support, networking configuration, service limits and cost.
Why this is not simply a GPU announcement
The AI hardware market increasingly features specialized accelerators, but usable system performance depends on memory and communication as well as compute. TechnologyHQ’s analysis of Microsoft’s Maia 300 AI accelerator explored how hardware designers optimize memory bandwidth and rack-level infrastructure for inference. Oracle’s networking update illustrates the complementary cloud-provider problem: keeping those compute resources supplied with data and recovering gracefully when paths degrade.
This is an engineering trend rather than proof that one cloud has the fastest AI infrastructure. Independent comparisons must account for accelerator models, interconnects, storage, software frameworks, job shapes and the cost of reserved capacity.
What Cloud Engineers Should Test Before Migrating Workloads
Evaluating Oracle Acceleron networking should begin with a workload profile. For distributed training, record collective-operation time, GPU utilization, network throughput, retransmissions or congestion indicators, tail latency, and end-to-end job duration. For inference, include time to first token, throughput at target concurrency, retrieval latency and service-level objective violations. For storage-heavy jobs, measure checkpoint load/save times and recovery after interruption.
Then ask Oracle which specific OCI shapes, regions, network interfaces, software versions and storage configurations support the announced capabilities. The press release includes a standard future-product disclaimer, and it does not provide a complete rollout matrix or price list. Do not assume every feature is generally available in every region simply because it has been announced.
A useful pilot should include controlled stress and failure cases. Compare steady-state performance with a busy shared network, induce an adapter or link failure in a permitted test environment, and measure recovery. Inspect whether existing applications can use the advertised RDMA verbs and whether the relevant collective-communication stack supports the OCCL plugin. Include engineering effort and operational complexity in the comparison.
Finally, calculate cost per completed workload, not only cost per accelerator-hour. A cluster with slightly more expensive networking can be economical if it substantially reduces wasted GPU time or restarts. But that outcome must be demonstrated with representative runs; the announcement alone cannot establish it.
Availability and What Remains Unverified
The October 27 material explains the new architecture and planned capabilities, but does not provide public, independent benchmark results covering all four announced areas. It also does not give universal pricing, a full region-by-region rollout schedule or an exhaustive compatibility list. Oracle’s future-product disclaimer explicitly says release timing and functionality may change.
Three questions remain especially important. First, how much does front-end RDMA improve real mixed-workload latency and throughput versus the same application without it? Second, how quickly does OCCL recover from network faults under sustained multi-node training? Third, which workloads and configurations produced the reported NVMe storage improvement of up to three times? These are testable questions, and answers would be more valuable than a generic promise of faster AI.
Frequently Asked Questions
What is Oracle Acceleron?
It is Oracle Cloud Infrastructure’s portfolio of networking and infrastructure technologies, including network fabrics, SmartNIC-based capabilities, software-defined traffic handling and security mechanisms. The October 27 announcement expands its support for AI data movement and resilient distributed communication.
Is front-end RDMA the same as GPU back-end networking?
No. A back-end fabric typically serves tightly coordinated accelerator communication, while a front-end network carries a broader mixture of compute, storage, application and external traffic. Supporting RDMA on the front end requires careful congestion and fairness controls.
What is OCCL?
OCCL is Oracle’s collective-communications network plugin. It aims to spread distributed AI traffic over healthier paths and provide failover when links, ports or network adapters fail. It does not replace the machine-learning framework or guarantee recovery from every kind of failure.
Will Oracle’s update make every AI workload three times faster?
No. The up-to-threefold claim concerns expanded NVMe block-storage attachment performance in unspecified configurations. It is not a benchmark for all AI training, inference or networking workloads.
Is the new functionality available everywhere now?
The announcement does not provide a complete general-availability or regional support matrix. Customers should verify support for their chosen OCI shapes, regions, storage services and software stacks before planning deployment.
The Bottom Line
Oracle Acceleron networking addresses a real bottleneck in AI infrastructure: when data movement is unpredictable, costly processors can sit idle and synchronized workloads can suffer from a single weak link. Front-end RDMA, SmartNIC-based congestion management, collective-aware path selection and multipath failover are technically coherent responses to that problem.
The remaining challenge is evidence at workload level. Oracle has described mechanisms and a limited performance claim, but customers still need reproducible benchmarks, compatibility details and pricing. For engineering teams, the best next step is not to assume a universal speedup; it is to test whether the network makes their own AI workloads faster, more resilient and less expensive to complete.
Ingrid Maldine is a business writer, editor and management consultant with extensive experience writing and consulting for both start-ups and long established companies. She has ten years management and leadership experience gained at BSkyB in London and Viva Travel Guides in Quito, Ecuador, giving her a depth of insight into innovation in international business. With an MBA from the University of Hull and many years of experience running her own business consultancy, Ingrid’s background allows her to connect with a diverse range of clients, including cutting edge technology and web-based start-ups but also multinationals in need of assistance. Ingrid has played a defining role in shaping organizational strategy for a wide range of different organizations, including for-profit, NGOs and charities. Ingrid has also served on the Board of Directors for the South American Explorers Club in Quito, Ecuador.